Whether to build or buy data management software for materials science depends on how distinctive your workflows are and who will own the system after launch. Building is easier to justify when a requirement is genuinely distinctive and has sustained funding and ownership. Buying usually fits when established products already cover the workflows and an internal build would largely recreate them.
An internal database can solve an immediate problem: organizing test results, tracking formulations, or preparing data for analysis. The harder question is whether your organization wants to own the software that supports those workflows over time.
Building and buying both require internal effort. The decision depends on what your laboratory needs, which capabilities distinguish your business, and who will maintain the system after its first release.
Define the scope before comparing options. A laboratory information management system (LIMS) for sample and test management is not the same project as a broader R&D platform that connects formulations, experiments, materials, analytical results, and predictive models. Without that distinction, cost and implementation estimates can describe very different systems.
Compare the complete commitment of building vs. buying
A build-versus-buy comparison should cover implementation, operation, and eventual replacement, not just development costs versus license fees.
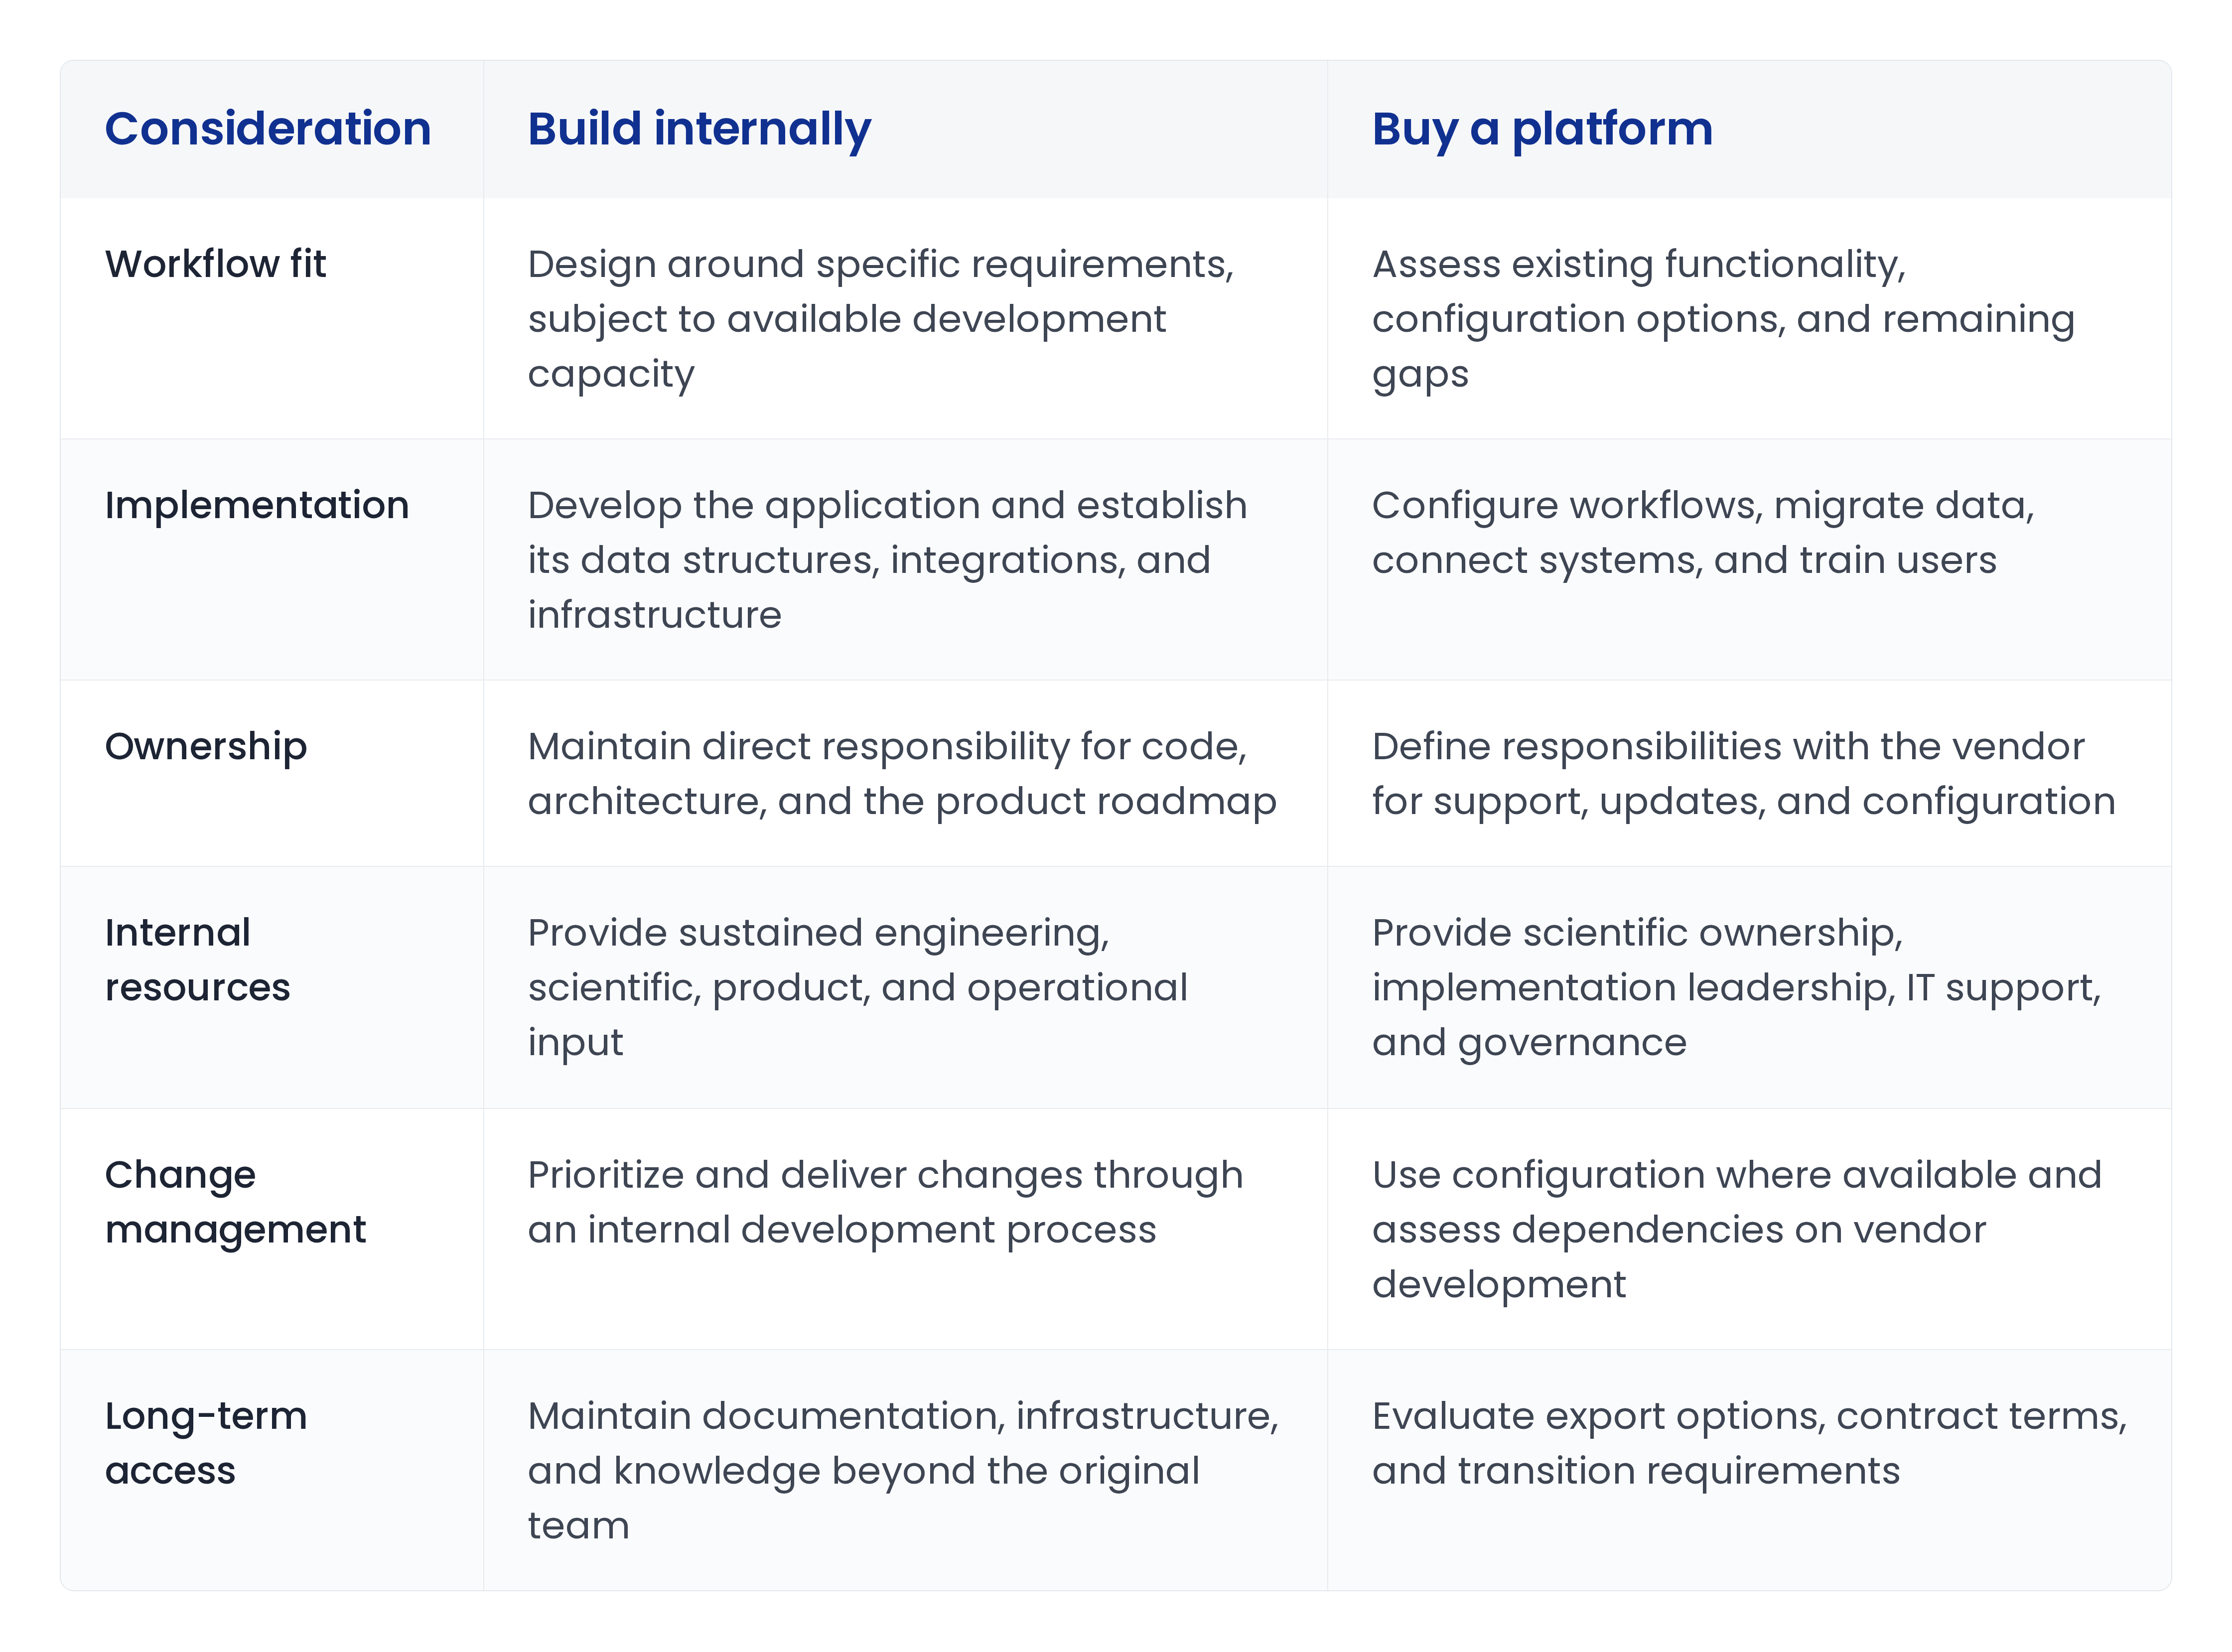
Neither option removes the need for clear data ownership and laboratory participation. A vendor cannot decide how your organization should identify samples, define properties, or govern changes to shared records. An internal engineering team needs those decisions too.
What building an internal R&D data platform requires
Treat an internal platform as a product, not a one-time development project.
The work needs ownership across requirements, data architecture, application development, integrations, infrastructure, security, testing, and user support. Scientists also need time to explain workflows, review designs, and test whether the system represents their work accurately.
These responsibilities do not necessarily require a separate full-time employee for each role. They do require named owners and enough capacity to deliver the agreed scope.
Budget for the work after launch: fixing defects, accommodating new instruments, updating dependencies, changing permissions, supporting additional sites, and helping users resolve problems. A system that depends on its original developer for every change is difficult to sustain.
What buying R&D data management software still requires
Buying software avoids developing the entire application yourself. It does not eliminate implementation.
Your team still needs to agree on data structures, prepare migration records, configure workflows, establish access controls, test integrations, and train users. The effort depends on the condition of existing data and the number of workflows and sites involved.
Ask vendors to separate the first usable deployment from the wider rollout. A limited implementation may support one team before the organization has resolved cross-site standards, historical migration, or additional integrations. Use those milestones to compare proposals rather than relying on a single launch date.
Test the workflow, not the demo
Start with representative work from your laboratory. Follow a formulation, sample, or experiment from creation through testing, review, analysis, and retrieval.
For example, a formulation team may need to trace a measured property back to the formula version, ingredient lots, processing conditions, and test method. Assess whether the proposed system preserves those relationships without forcing scientists to reconstruct them later.
Include exceptions: a repeated test, a corrected result, a changed method, an unavailable instrument, or a user who should not have access to a project. These reveal requirements that a straightforward demonstration may miss.
Distinguish a pilot from a production system
A lightweight database or open-source tool can be a sensible way to test a workflow or analytical approach. The pilot should answer a defined question, such as whether existing data can support a model or whether a proposed structure represents experimental work.
Before expanding it, assess what is missing for routine use. That may include permissions, audit history, recovery procedures, integration monitoring, documentation, and support.
Keep the data portable during the pilot. If the project succeeds, you should be able to move its records into the chosen production system without losing identifiers or experimental context.
Assess data reuse and machine learning separately
Preserving files, comparing results, and developing predictive models are related tasks, but they are not interchangeable.
Decide which records need to be searchable and structured. A report attached to an experiment may preserve useful evidence while still requiring manual work to compare its results with other experiments.
If machine learning is in scope, define the problem it should address. Then assess whether the data contains the inputs, outputs, units, conditions, and provenance needed for that work. Do not make model deployment a requirement simply because the project is described as materials informatics, the use of data science and machine learning to guide materials development.
Build a defensible business case
Compare both options over the same scope and planning period. Include internal labor, migration, integrations, infrastructure, support, training, upgrades, and licensing where applicable.
Account for the work displaced by the project. Assigning scientists or engineers to platform development means less capacity for other responsibilities. That tradeoff may be worthwhile, but it should be visible.
Measure the cost of waiting against current problems rather than hypothetical competitors. Useful questions include:
- How much time do scientists spend finding, cleaning, or re-entering data?
- Which projects are delayed by unavailable records or disconnected systems?
- How often is work repeated because previous results cannot be retrieved?
- Which cross-site comparisons require manual reconciliation?
- What could a limited first deployment improve?
An internal build may be justified when a requirement is genuinely distinctive, cannot be met adequately through available products, and has sustained funding and ownership.
Buying may be the better choice when established functionality covers the required workflows and internal development would largely recreate it. A combined approach is also worth considering: use a platform for shared records and routine workflows while retaining internal ownership of specialized analysis or models.
Before approving either route, establish who owns the roadmap, who supports users, and how the organization will retain access to its data if the system changes.
Common build-versus-buy mistakes
Most build-versus-buy decisions go wrong for the same few reasons, whichever route the organization chooses.
- Comparing a prototype with a product. A spreadsheet macro or small database that works for one team is set against a full platform proposal, even though the prototype has no permissions, audit history, or support model yet.
- Leaving out the people cost. The business case counts licenses or developer salaries but not the scientists who must define workflows, test the system, and answer questions after launch.
- Deciding before defining the data. Teams choose a route before agreeing how samples, materials, properties, and units should be identified, so the same disagreements resurface during implementation.
- Assuming the first release is the finished system. New instruments, sites, and projects keep arriving. Whichever option is chosen, someone has to own the changes they bring.
- Ignoring the exit. Few plans consider how records would be exported or moved if the system is replaced, whether it was built internally or bought.
For example, a polymer team that builds a quick results database for one product line may find it works well until a second site wants to use it with different test methods. At that point the questions about identifiers, ownership, and support that were skipped at the start become the main project.
Evaluate Uncountable against your requirements
Assess Uncountable using the same workflow evidence and cost criteria you would apply to an internal build or another vendor.
Bring representative records and a short list of requirements. Ask the team to show what the proposed setup supports, which parts require configuration or integration, and where gaps remain. Request an implementation plan that identifies responsibilities on both sides.
The decision should come from that assessment, not from a general promise that building is risky or buying is effortless.
Book a demo of Uncountable to discuss your R&D workflows, data requirements, and implementation scope.